Model-Based vs Model-Free RL for Game-Domain Training
Model-based RL wins on sample efficiency; model-free RL handles complex environments better.
Model-based and model-free reinforcement learning solve the same problem through different architectures, and the choice between them in game-domain training comes down to sample efficiency, compute cost, model availability, and how complex the environment actually is. Neither approach is categorically better. Each wins under specific, identifiable conditions, and the rest of this piece lays out what those conditions are.
What model-based and model-free RL are doing differently
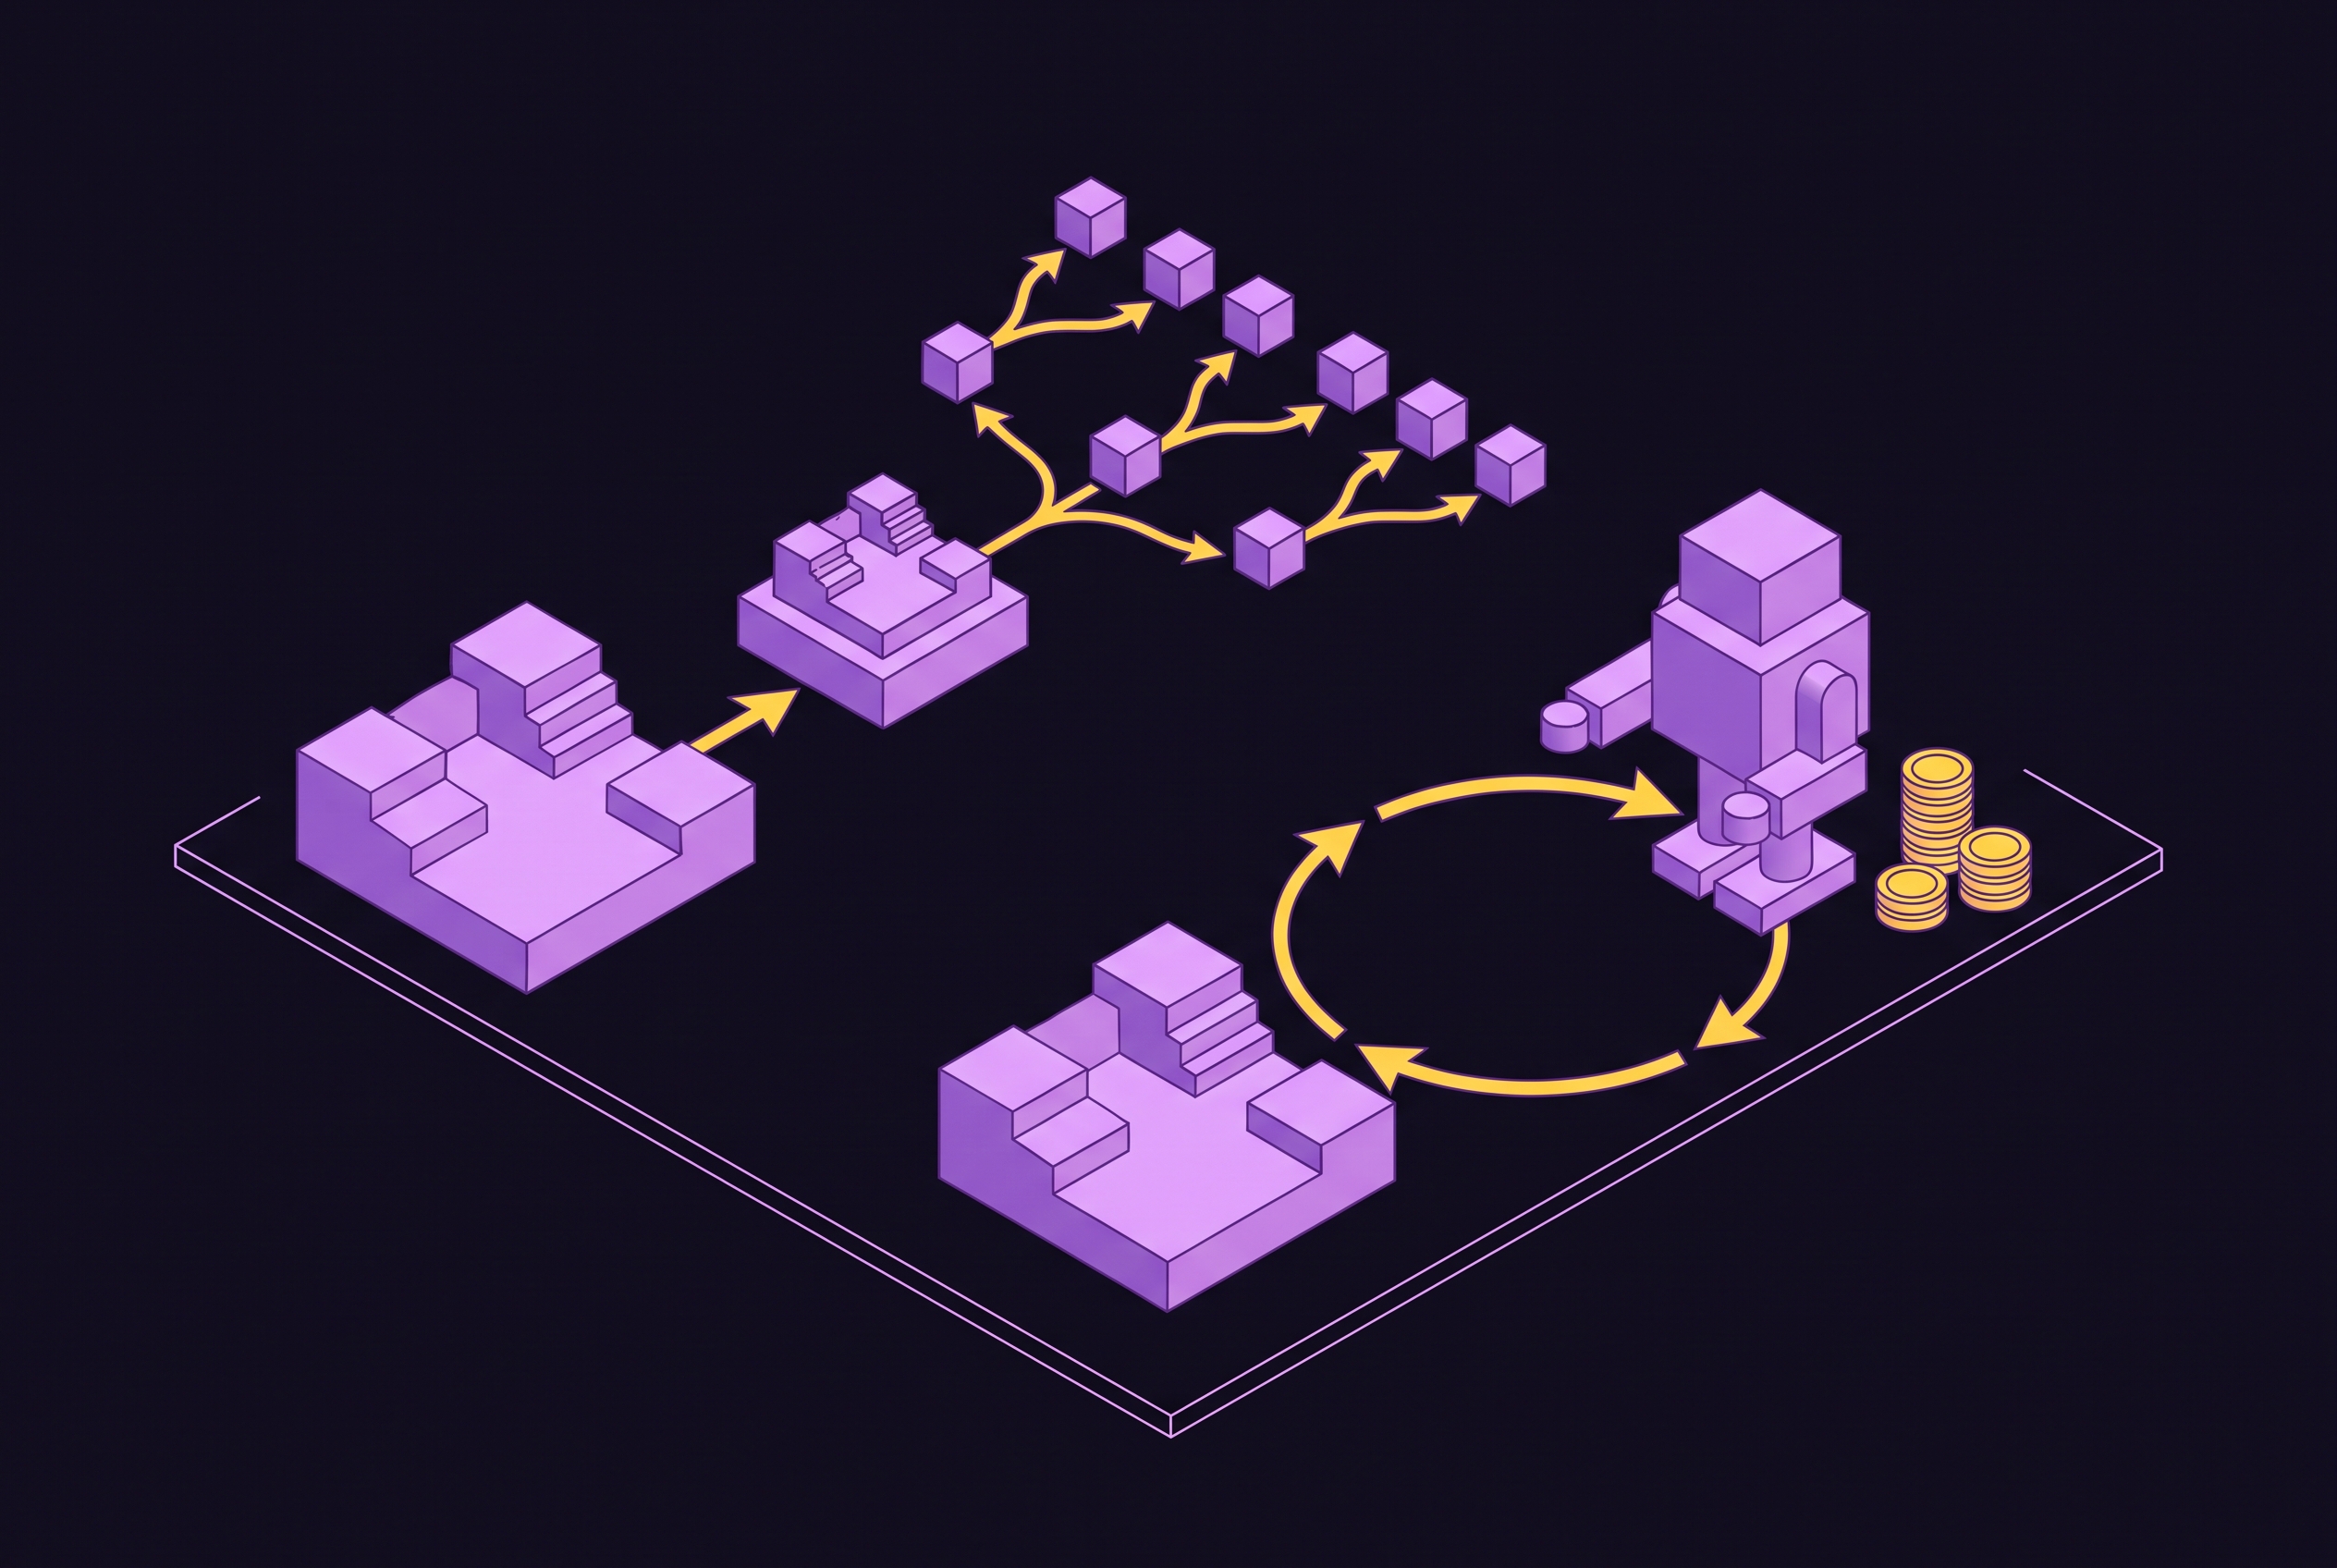
The split between these two families of algorithms is architectural, a matter of different mechanisms rather than one producing better scores than the other. Model-based RL builds an internal representation of how the environment transitions from state to state and what rewards those transitions produce, then uses that representation to plan ahead before committing to an action. Model-free RL skips that step. It improves a policy or a value function directly from experience, updating based on what actually happened.
The practical mechanics differ accordingly. A model-based agent constructs trajectories through its internal model, essentially running "what if" scenarios before it acts in the real environment. A model-free agent interacts, observes an outcome, updates its policy, and moves on. There's no internal rehearsal step. Algorithms fall into the model-based camp precisely because they depend on having some representation of the world to search or iterate over, building and consulting that internal structure before acting.
One detail determines a great deal of what follows: the model itself can be given to the agent or it can be learned by the agent. Chess and Go belong to the first category. The rules are fixed, fully known, and available to the system from the start, so planning happens over a perfect representation of the world. Atari games and open-world environments belong to the second category. No one hands the agent a rulebook. It has to infer how the world behaves from raw pixels and its own trial-and-error experience. That single distinction, given model versus learned model, is the foundation for almost every tradeoff discussed in the rest of this piece.
Sample efficiency as the central pressure point in game-domain training
If you don't have access to industrial-scale compute, you can't wait for a model-free algorithm to converge the way DQN does. That constraint, not an abstract preference for elegance, is why sample efficiency drives so much of the architecture decision in game-domain RL. DQN needs millions of frames of gameplay, often translating to many tens of hours of real-time play, before it reaches a usable policy. That cost is the baseline every alternative gets measured against.
Model-based RL responds to that cost directly. It lets the agent generate synthetic experience inside its learned model, so it doesn't have to generate every unit of experience by interacting with the real environment. The agent can "practice" without burning additional environment interactions, which matters because the simulator itself is often the bottleneck, not the learning algorithm.
Games present this pressure more acutely than many other RL domains. Simulating a game environment at scale often costs a lot in compute and time, and the action space can be so large that random exploration simply takes too long to stumble onto useful behavior. Planning compresses what would otherwise demand a much larger number of environment steps, and research on model-based generalization backs this up: model-based approaches reach near-optimal performance faster precisely because planning substitutes computation for data collection. That makes sample efficiency more than a matter of convenience. So many teams building game-playing agents start by asking not which algorithm scores highest, but which one they can actually afford to run to convergence.
The liability model-based RL carries in exchange for that efficiency: compounding error
Model-based RL's efficiency advantage comes with a condition attached: the model has to be accurate. When it isn't, the agent plans over predictions that drift further from reality with every step it projects forward. Small inaccuracies in a single transition compound across a multi-step rollout, and the agent can end up systematically steering toward decisions that looked good inside the model but fail badly in the real environment.
The mechanism is straightforward. The agent plans from the model's output, so each predicted step feeds into the next one. Over a short horizon, a small error barely matters. Over a long horizon, that same small error multiplies into a misdirection large enough to produce a bad policy. Games with dense hidden interactions, stochastic dynamics, or rules that resist clean approximation make this worse, because you can't easily learn an accurate model for them. In those environments, model-based RL can end up performing worse than the model-free methods it was supposed to outpace.
The field's response has not been to simply demand better models. It has been to design architectures that contain the damage a flawed model can do. DreamerV3, built by Google DeepMind researcher Danijar Hafner and collaborators, limits its imagined rollouts to a short, fixed horizon and lets a learned critic stand in for longer-horizon prediction, which bounds how far any single error can propagate before it gets corrected. That's part of why DreamerV3 can reach human-level performance on more than 150 diverse tasks with just one set of hyperparameters. MBPO takes a related approach: it keeps rollouts short and trains a model-free algorithm, Soft Actor-Critic, on a mix of real and model-generated data, which lets it match top model-free returns while using roughly a tenth of the environment interactions those methods would otherwise require. MuZero attacks the problem from a different angle. Rather than modeling raw pixels, it learns a latent-space dynamics function, a representation function, and a prediction function, planning in a compressed latent space where there is simply less surface area for error to take hold.
Compounding error is a manageable cost when the environment is structured and reasonably predictable. It becomes the dominant failure mode the moment the environment is dense with hidden interactions that resist being captured in a model.
Model-free RL's strengths: asymptotic performance and environment complexity
Model-free RL is the structurally correct choice in specific conditions: environments too complex or too stochastic to model reliably, paired with enough data to make the sample-efficiency gap irrelevant. When those conditions hold, model-free methods can reach a higher ceiling, because model-based approaches stay held back by an imperfect internal model.
The limitation runs in both directions. Model-based RL can reach near-optimal control quickly, but only within a narrow class of dynamics that are structured and predictable enough to model well. But step outside that class, and if you have enough data, model-free methods pull ahead. They're also simpler to build. There's no model-learning infrastructure to maintain, and performance scales with data volume in a way that's easier to predict and reason about.
The SimPLe benchmark, built by Google Brain in 2019 and tested on Atari, shows exactly this pattern. In the low-sample regime, SimPLe's model-based approach beats Rainbow, which is a model-free algorithm. As more data becomes available, that advantage shrinks and eventually disappears: tuned Rainbow variants end up roughly on par with SimPLe, each outperforming the other across about half of the 13 games tested at the standard 100,000-step budget. The advantage was conditional on the data regime the whole time.
More recent work pushes the same point further. MR.Q, evaluated at ICLR 2025 across 118 environments spanning four major RL benchmarks, was built and tested directly against DreamerV3 and TD-MPC2 as a general-purpose model-free alternative. The MR.Q paper notes that DreamerV3 relies on far more parameters to achieve its results, which raises a real question about how much of model-based RL's apparent advantage comes from the paradigm itself versus simply from scale. KLENT, a 2025 paper on resource-efficient model-free RL for board games, makes a related case, but from a different direction. It proposes a model-free policy optimization algorithm that eliminates look-ahead search during training entirely, and tests it across five board games: Animal Shogi, Gardner Chess, 9x9 Go, Hex, and Othello. The result matters because board games are exactly the domain where search-based methods like AlphaZero have dominated. KLENT shows that even there, you can learn efficiently with far fewer compute resources than search demands.
How the game environment's structure determines which tradeoffs dominate
Choosing between these two paradigms isn't a matter of taste. It follows from concrete properties of the game environment itself, and several of those properties do most of the work in determining which approach fits.
Whether the model is given or has to be learned is the first and most consequential of these. AlphaZero's superhuman performance in chess, shogi, and Go comes directly from exploiting a perfect, given rule-set: planning happens over ground truth, compounding error has nowhere to enter, and the result is a system that simply outperforms human play. The moment no model is given, the agent has to learn one from experience, and the cost and reliability of that learning process become the variables that matter most.
Environment complexity is the second. Games built around stochastic elements, hidden state, or dense emergent interactions resist accurate model learning almost by definition, which pushes the balance toward model-free methods regardless of what sample efficiency gains a model-based approach might otherwise offer.
Data regime is the third, and the SimPLe result is the clearest illustration available: an advantage for model-based methods in the low-sample regime that disappears once enough data accumulates and model-free methods catch up.
Compute access is the fourth. Search-based model-based methods like AlphaZero carry a real cost: training AlphaZero has been reported at more than 10 GPU-years, a figure that puts it out of reach for most teams and creates a genuine reproducibility barrier in the field. KLENT and MBPO both demonstrate that this isn't an inherent property of either paradigm. Careful design can make both model-based and model-free approaches dramatically more resource-efficient.
Action space structure rounds this out. Discrete, finite action spaces, the kind board games present, suit planning-based search well. But when action spaces are large, continuous, or partially observable, the balance shifts toward model-free or hybrid approaches, because exhaustive planning stops being tractable.
Hybrid architectures and scaled world models as the current research frontier
The most active work in the field is about building architectures that capture model-based sample efficiency while holding onto the asymptotic performance and robustness that model-free methods are known for. EfficientZero V2 and JOWA, both recent results, show where that convergence is heading.
MBPO remains the clearest early template for this kind of hybrid: a learned model generates short synthetic rollouts, and a model-free algorithm, Soft Actor-Critic, trains on a blend of real and model-generated data. The short rollout horizon isn't incidental. It caps how far compounding error can spread while it still preserves most of the sample efficiency gain. MuZero extends the same logic by removing the requirement for a given environment model entirely, learning latent-space dynamics through a representation function, a dynamics function, and a prediction function, which lets it retain AlphaZero's planning strength without AlphaZero's dependence on known rules.
EfficientZero V2, published in 2024, outperforms the prior state of the art by a significant margin under limited-data conditions, producing superior results on 50 of 66 evaluated tasks across Atari, Proprio Control, and Vision Control, and surpassing DreamerV3 in the process. JOWA, presented at ICLR 2025, pushes in a related but distinct direction: a scaled, offline, model-based agent pre-trained across multiple Atari games. The largest JOWA agent reaches strong human-level performance on the games it was pre-trained on using only a small slice of offline data, and it transfers to entirely new games using just a handful of offline fine-tuning trajectories per game. That result says something larger about where model-based RL is headed: scaling and offline pre-training are opening operating modes for model-based methods that didn't exist before.
A cluster of transformer-based world models fills out the picture of how varied this architectural space has become. IRIS builds an autoregressive transformer over discrete tokens. DIAMOND uses diffusion-based world simulation. EMERALD applies masked generative transformers over spatial latent states. Each takes a different route to the same goal, narrowing the gap between what a learned model predicts and what the real environment does. World models are also starting to separate from reinforcement learning as their own research object, and they now feed into video generation and multi-modal systems well beyond game-playing agents. The part of model-based RL concerned with learning a model of the world is turning into its own research area.
A practical framework for selecting an approach given your game domain's constraints
Four constraints decide which approach to use in game-domain RL: whether a model is available, how complex the environment is, how much data the project can afford to collect, and how much compute is actually on hand. Each one maps onto a specific structural advantage that one paradigm holds over the other.
Where the environment model is given and the rules are complete, as in chess or Go, model-based planning through MCTS or AlphaZero-style search is the natural starting point. The planner operates over ground truth rather than a learned approximation, so compounding error isn't a concern here.
Where the model has to be learned but the environment is structured and low in stochasticity, hybrid methods like MBPO, MuZero, and EfficientZero V2 offer the better balance. Short rollouts give you synthetic experience, so you get sample efficiency gains, and errors don't build up across a long horizon.
Where the environment is highly complex, stochastic, or dense with hidden interactions, model-free methods such as DQN, PPO, or SAC, or general-purpose approaches like MR.Q, are the structurally safer choice. No learned model exists to introduce cascading error, so performance scales predictably with however much data you have.
If data is severely limited, model-based or offline pre-trained approaches like JOWA and EfficientZero V2 offer the sharpest gains, because every additional environment interaction costs you the most there.
Where compute is the binding constraint, model-free approaches, KLENT for board games or SAC-based methods for continuous domains, strip out the search overhead that makes AlphaZero-style training demand upward of 10 GPU-years. KLENT's result proves you can do this even in domains, like board games, that search-based methods have dominated for years.
The clearest lesson out of the 2025 research is that treating this as a binary choice, model-based or model-free, undersells how the field is actually operating. Most of the strongest recent results come from architectures built deliberately to sit at a specific point on the efficiency-accuracy tradeoff curve, rather than from a commitment to one pure paradigm over the other.
Sources
- Resource-Efficient Model-Free Reinforcement Learning for Board Games
Provided the KLENT paper's findings on resource-efficient model-free RL for board games, including the 10 GPU-years training cost for AlphaZero and the five board games tested.
- SCALING OFFLINE MODEL-BASED RL VIA JOINTLY
Provided details on JOWA, the scaled offline model-based agent pre-trained across multiple Atari games presented at ICLR 2025.
- The Benefits of Model-Based Generalization in Reinforcement Learning
Supported the claim that model-based approaches reach near-optimal performance faster because planning substitutes computation for data collection.
- A Survey on Model-based Reinforcement Learning
Provided survey-level grounding for how model-based RL constructs and uses internal environment representations for planning.
- Model-Based Reinforcement Learning for Atari
Provided the basis for the SimPLe benchmark discussion, including its comparison with Rainbow on Atari under limited data budgets.
- Learning to Combat Compounding-Error in Model-Based Reinforcement Learning
Provided the conceptual basis for the compounding error problem in model-based RL and the architectural responses to it.
- Published as a conference paper at ICLR 2025 TOWARDS GENERAL-PURPOSE MODEL-FREE
Provided details on MR.Q, the general-purpose model-free algorithm evaluated at ICLR 2025 across 118 environments as an alternative to DreamerV3 and TD-MPC2.