Procedural Level Generation for Infinite Training Diversity
Procedural generation keeps RL agents from overfitting to fixed training environments.
Reinforcement learning agents trained on a fixed set of levels tend to learn shortcuts that work only inside that set. Procedural level generation fixes this by feeding agents a stream of new, never-repeated configurations during training, so the only policies that survive are the ones that generalize.
Why RL agents trained on fixed environments fail to generalize
A fixed training environment hands an agent a fixed distribution, and an agent that keeps encountering the same handful of configurations has no reason to learn anything beyond what solves those configurations. It finds the shortcut that clears the obstacles it has actually seen, and it stops there, because nothing in the training signal rewards a more general solution. So you get a policy that looks competent during training but falls apart the moment the environment shifts even slightly.
The Arcade Learning Environment has functioned as a gold standard for RL research for over a decade, yet it carries the same risk as any other static benchmark: when the environment doesn't vary enough, the learning algorithm settles for a policy tuned to one particular configuration rather than one that holds up broadly. Train an agent to drive through mountainous terrain, and it can perform at an arbitrarily poor level in flat terrain. The policy works, but only inside the narrow slice of the world it was shown.
This isn't a marginal footnote. Agents have shown they can overfit even to remarkably large training sets, which raises an uncomfortable possibility: overfitting may be present across many of the benchmarks the field treats as settled. And the failure mode is not confined to game-playing agents. Fixed reasoning-task datasets used in language model post-training show something researchers call diversity collapse, where a dataset looks varied on its surface but its tasks cluster around one or two failure modes. Running more passes over that same fixed set of tasks didn't improve performance and eventually made it worse, a result that points toward a simple rule: more task diversity helps more than more epochs on the same tasks.
What procedural level generation does to the training distribution
Procedural level generation changes the object an agent trains against. Instead of a finite, hand-built set of levels that eventually gets memorized, a generator produces new instances continuously, so the agent never runs out of fresh configurations to solve. The training distribution becomes a moving target instead of a fixed one, so an agent can no longer rely on seeing the same handful of configurations repeatedly.
Procgen, built by Cobbe and colleagues at OpenAI, turned this idea into a formal benchmark. It uses procedural content generation to keep supplying a shifting pool of environments, so agents have to build policies that hold up across many different level layouts, visual styles, and dynamics. Procgen's authors also used the benchmark to study scaling, and they found that larger models improve both sample efficiency and generalization by meaningful margins. So PCG-driven diversity and model capacity reinforce each other rather than working against each other.
None of this is a new idea borrowed from nowhere. Level generation goes back to Beneath the Apple Manor, written by Don Worth in 1978, and to Rogue, built by Michael Toy and Glenn Wichman in 1980. Commercial games have used it for decades since: Spelunky (Derek Yu, 2008), Minecraft (Mojang, 2011), Starbound (Chucklefish, 2016), and No Man's Sky (Hello Games, 2016) all rely on procedural generation to keep their worlds from feeling repeated. The RL community adopted a tool game designers built to keep players coming back, and repurposed it to keep agents from settling.
The goal in an RL context differs from the goal in a shipped game, though. A game's procedural generator usually aims for variety that looks and feels good to a human player. An RL training generator aims for functional variability: levels that differ in the ways that actually force new behavior, not levels that merely look different while posing the same underlying problem. That distinction is what breaks the cycle of shortcut learning described above.
The spectrum of PCG approaches for RL training, from random generation to adaptive curricula
"Procedural generation" names a family of methods, not one technique, and the methods differ in how much they cost to build, how much ground they cover, and how well they track what a given agent is actually ready to learn. Each later method in this progression exists to fix a specific limitation of the one before it.
The simplest layer is domain randomization: generate large numbers of levels by randomizing parameters like terrain, object placement, or physical constants. It's cheap to implement and it delivers breadth almost for free, but the generator has no sense of the agent's current skill. It will produce levels that are trivially easy and levels that are functionally unsolvable with the same indifference, because nothing in the method asks whether a given level is appropriately challenging for where the agent currently stands.
PCGRL, short for PCG via Reinforcement Learning, answers that gap by training a generator rather than hand-coding one. An RL agent learns to build levels through local, iterative edits aimed at maximizing functional metrics the designer specifies, rather than copying patterns from a dataset of human-made levels. It was first applied to mazes, a simplified Zelda, and Sokoban, and its appeal is that it sidesteps the need for large libraries of human-authored levels while still training the generator against explicit functional constraints rather than surface appearance. Jiang and colleagues at NYU Tandon extended PCGRL into three-dimensional Minecraft domains in 2022, and it handles tasks involving gravity, multi-dimensional movement, and paths that can't simply be reversed. Their PCGRL agents generated complex, varied levels and generalized to random initial states, and the authors argue these generators can double as pre-trained environment generators inside a curriculum for training player agents.
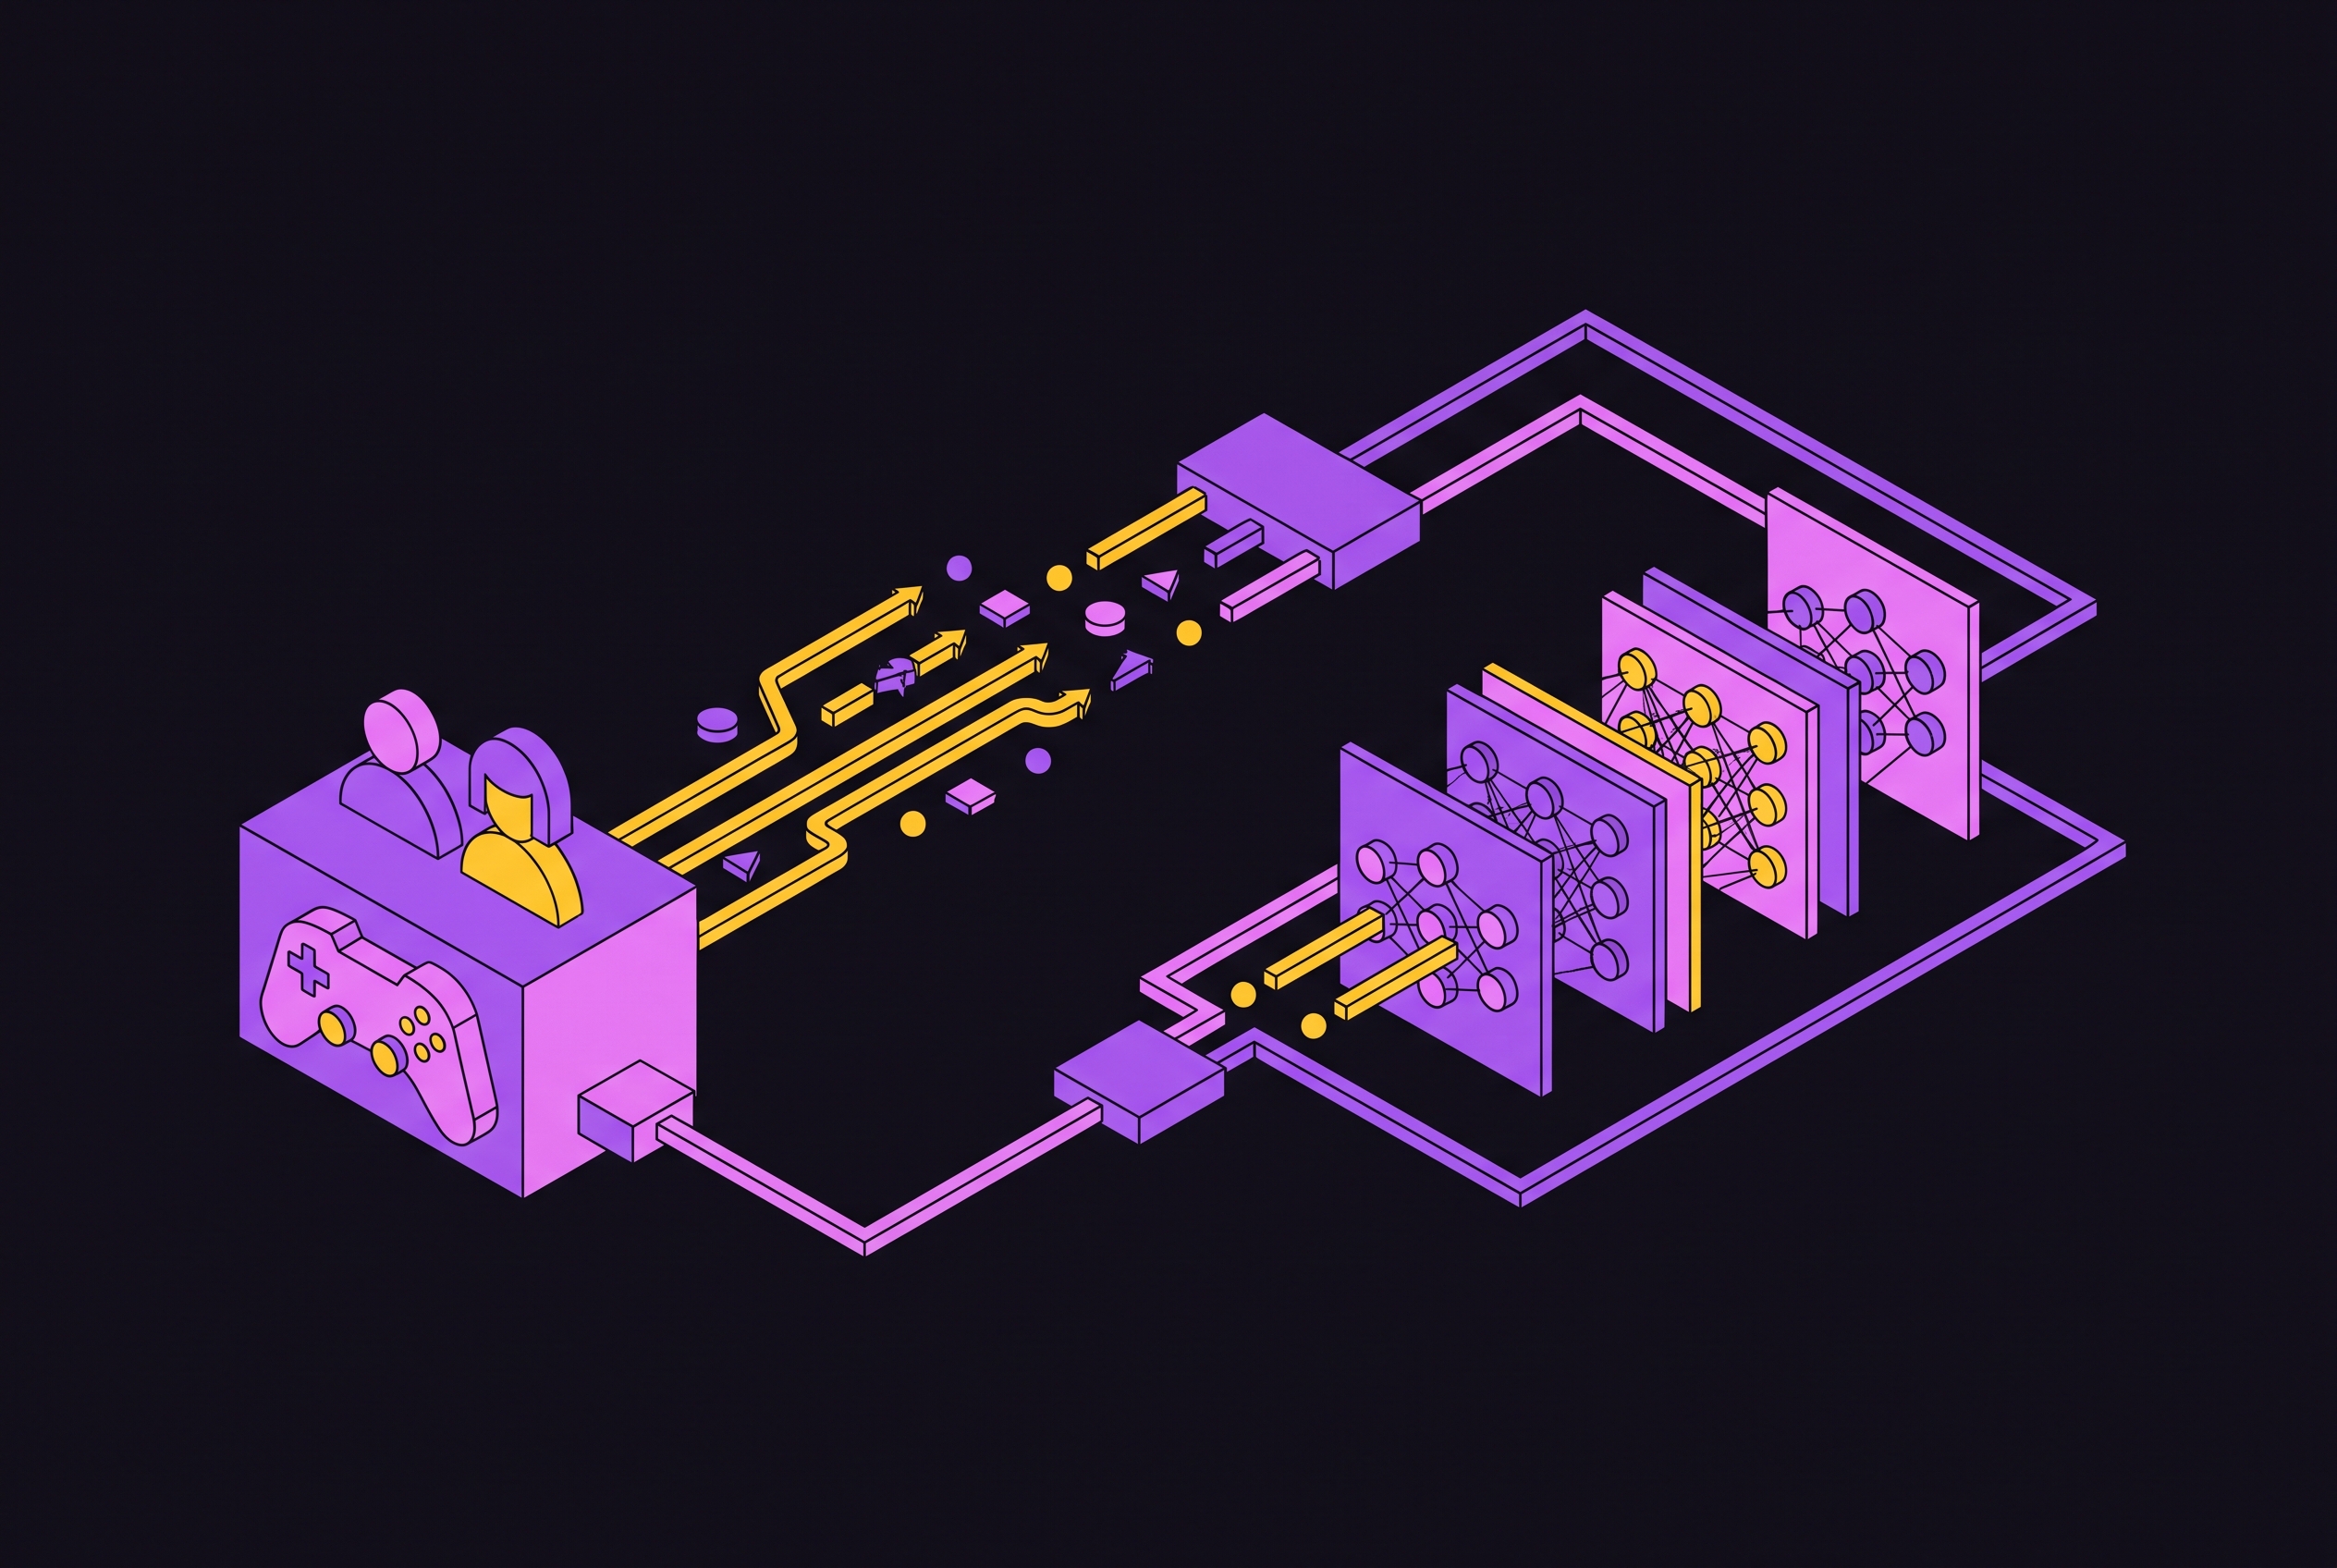
Unsupervised Environment Design, or UED, adds the piece domain randomization and PCGRL both lack: adaptiveness to the agent's current capability. An underspecified environment carries free parameters, so UED adjusts those parameters as training proceeds, and the agent keeps meeting levels near the edge of what it can currently handle, not levels picked without regard to its progress. PAIRED, introduced by Dennis and colleagues in 2020, frames this as a three-way adversarial game: a teacher that generates levels, an antagonist student that represents expert performance, and a protagonist student that represents the agent actually being trained. The gap between antagonist and protagonist performance is the signal that steers the generator toward useful difficulty. Prioritized Level Replay takes a different route to the same goal: it replays previously seen levels chosen by their estimated learning potential using Generalized Advantage Estimation, and it has shown itself to be more scalable than PAIRED while producing more robust performance outside the training distribution. Diversity-UED adds a further correction: UED methods can repeatedly select environments that look different on the surface but repeat the same underlying challenge, so Diversity-UED introduces an explicit distance measure between environments to push the generator toward variety that's actually meaningful rather than cosmetic.
What zero-shot transfer results from UED experiments reveal
The empirical record backs the theoretical case for UED, though the size of the gain depends heavily on the setting. PAIRED produced meaningfully higher zero-shot success rates in Labyrinth and Maze testbeds than the baselines it was compared against, and those baselines clustered near zero. You get a real improvement over what came before, even though it still falls well short of robust, general-purpose performance.
PLR's advantage over PAIRED in scalability carries practical weight beyond the benchmark numbers: a method that scales is a method that can actually get used in production training pipelines, where a theoretically elegant but computationally fragile approach tends to get set aside.
More recent work has pushed the same logic further. ATLAS, published at AAAI in 2026, extends curriculum generation to cover both tasks and levels at once, representing tasks as reward machines, finite-state machines that compactly encode a reward function. Earlier UED work generated curricula over levels for just one fixed task, so general-purpose agents had no matching curriculum over the tasks themselves. ATLAS outperforms random sampling by a wide margin, and the gap is largest in settings where stumbling onto a solvable combination of task and level by chance is unlikely.
The same underlying failure extends past single-agent games. The Overcooked Generalisation Challenge, published in Transactions on Machine Learning Research in September 2025, is the first open-source benchmark built to measure overfitting in cooperative multi-agent RL. Agents trained in that setting tend to overfit to the particular spatial layouts, interaction bottlenecks, or object placements they saw in training, without learning coordination strategies that carry over to new environments. OGC turns that failure into something measurable and comparable across methods, rather than an anecdotal complaint about multi-agent training.
Three live objections that practitioners raise against PCG-based training
PCG-based training rests on three tensions the field has not closed. Raw variety is not the same thing as the right kind of variety. Reward design remains a manual bottleneck no generator solves by itself. Adversarial generation methods carry real instability risks.
The first objection concerns surface diversity. A training set can look diverse on its surface while its levels cluster around one or two failure modes, the same trap you saw earlier with language model post-training. Diversity-UED's explicit distance measure addresses part of this, but what actually counts as a meaningfully different configuration versus a cosmetically different one is still an open question. Competitive coevolution, where environments evolve to challenge agents and agents evolve to solve those environments, has been proposed as one route toward diversity that's functionally meaningful, not just superficial.
The second objection concerns reward design. Generating levels procedurally says nothing about what makes a given level good training material. Specifying a reward scheme or evaluation function that captures what a designer wants is still hard, and evolutionary methods and RL-based approaches have both been tried, but no general solution exists yet. Automating this specification with language models introduces a new failure mode of its own: a reward function generated from a natural-language description can be misspecified in ways that aren't obvious until training has already gone wrong.
The third objection is specific to PAIRED's adversarial structure. The protagonist and antagonist agents in that three-way game can learn to collude, which degrades the quality of the challenges the generator produces and weakens the training signal the whole method depends on. This is a documented instability in the adversarial UED paradigm, confirmed in empirical studies.
A fourth friction sits outside the technical literature, in adoption. A 2026 survey of 120 game development professionals found a statistically significant gap between how often artists and designers use procedural generation, with artists adopting it far more. The same survey found that developers value creative control and process transparency over automation when they judge generative AI tools. Reduced control has limited how widely PCG tools get adopted in production, and that same tension applies directly to RL researchers who want to bring these methods into real training pipelines rather than research demos.
LLM-Driven Generation and Learned World Models
The newest wave of PCG research targets the two bottlenecks the objections above describe: reward specification and environment simulation, both of which have historically needed manual expert work to get right.
PCGRLLM, submitted by Baek and colleagues in February 2025 and revised in May 2026, automates reward specification through a three-step sequential process. It refines the reward function using feedback, aligns that reward function to the environment and trains the agent against it, then feeds back further based on the content the agent actually generates. The method uses chain-of-thought, tree-of-thought, and graph-of-thought prompt engineering to drive this loop, and when the feedback loop is included, relative accuracy improves by as much as 415 percent over zero-shot baselines. The feedback architecture is built specifically to catch reward misspecification before it propagates through training, which directly answers the risk raised by LLM-generated rewards in the previous section.
A second line of work, from Kaijie Xu and Clark Verbrugge, presented at the FDG PCG Workshop in 2026, targets what the paper calls infinite-skill generation. It tests local open-weight language models against deterministic, template-based, random, and calibrated sampler baselines, across a large configuration corpus and multiple metrics. The local language models hit near-perfect coherence between generated elements while keeping high diversity within a given configuration, and none of the baseline methods matched that combination.
A third direction replaces hand-coded simulators with learned environment representations. Recent UED research has explored generating environments through diffusion models, as in Chung and colleagues' 2024 work, and through learned world models, as in Güzel and colleagues' 2025 work. Both represent a shift from simulators built by hand toward environment representations learned directly from data, a change that, if it holds up, removes the need to manually specify a simulator for each new training domain.
Measuring diversity is as hard as generating it
Generating varied levels is only one half of the problem. The field still lacks an agreed way to measure whether generated content is diverse in the ways that actually matter for agent generalization, and conflating different diversity metrics produces conclusions that don't hold up.
Diversity itself has more than one dimension. Content-based metrics track structural variety in a level's geometry, while player-centered metrics track variation in how a player, or an agent, has to behave to succeed. These two kinds of variety can conflict with each other, reinforce each other, or do both at once depending on the level. Zhang and colleagues formalize this by treating each diversity metric as its own distinct objective and training generators to sit along the Pareto front across multiple dimensions at once, a method demonstrated on Super Mario Bros. rather than collapsing everything into one number the way a weighted-sum approach does. A weighted sum hides exactly the tradeoffs that matter for downstream agent training, because it forces several independent kinds of variety into a single score and discards the information about where they disagree.
Testing three baseline algorithms, a random generator, an evolution strategy, and a genetic algorithm, shows that some PCG problems are easier to solve than others, and that the objective a researcher chooses has a measurable effect on the quality, diversity, and controllability of what gets generated. The benchmark built around this comparison is extensible, meaning researchers can add further PCG problems to it over time, which matters directly if the field decides it needs evaluation criteria built specifically for RL training rather than borrowed from game design.
A 2026 paper on Minecraft voxel generation pushes this evaluation question further by identifying three distinct regimes of constraint learnability: Controllable, Approachable, and a third regime describing structural constraints a generator struggles to enforce reliably. That framing matters because it tells practitioners which kinds of structural rules they can expect a generator to actually respect, and which kinds remain outside what current methods can guarantee. Generation and measurement have to improve together. A generator that produces endless new levels without a reliable way to check whether those levels are diverse in the ways that matter leaves practitioners unable to tell whether the training distribution they built actually overfits less, or just overfits in a more elaborate way.
Sources
- Learning Controllable 3D Level Generators
Provided details on extending PCGRL into 3D Minecraft domains, handling gravity and multi-dimensional movement, and the argument that generators can serve as pre-trained environment generators for curriculum learning.
- PCG Workshop
Sourced the 2026 survey of game development professionals on procedural generation adoption, the finding about artist vs. designer usage gaps, and the constraint learnability regimes identified in Minecraft voxel generation research.
- Expanding Horizons of Level Diversity via Multi-objective Evolutionary Learning
Provided the multi-objective approach to level diversity using Pareto fronts across multiple diversity metrics, demonstrated on Super Mario Bros.
- Compressing and Comparing the Generative Spaces of Procedural Content Generators
Supplied the baseline algorithm comparisons (random generator, evolution strategy, genetic algorithm) and the finding that the chosen objective measurably affects quality, diversity, and controllability of generated content.
- Leveraging Procedural Generation to Benchmark Reinforcement Learning
Provided the core description of Procgen as a formal benchmark using procedural content generation, and the finding that larger models improve both sample efficiency and generalization.
- PCGRLLM: Large Language Model-Driven Reward Design ...
Described the PCGRLLM method for automated reward specification using chain-of-thought prompting and iterative feedback, and the 415 percent accuracy improvement over zero-shot baselines.
- Prioritized Level Replay
Provided the description of Prioritized Level Replay as a more scalable alternative to PAIRED that replays levels by estimated learning potential using Generalized Advantage Estimation.
- Procedural Content Generation via Reinforcement Learning
Sourced the original PCGRL method description, including its application to mazes, Zelda, and Sokoban, and the approach of training a generator through local iterative edits against functional metrics.