Zero-Shot Transfer of Game Policies Across Procedurally Varied Levels
Policies trained on narrow conditions collapse on unfamiliar levels without retraining.
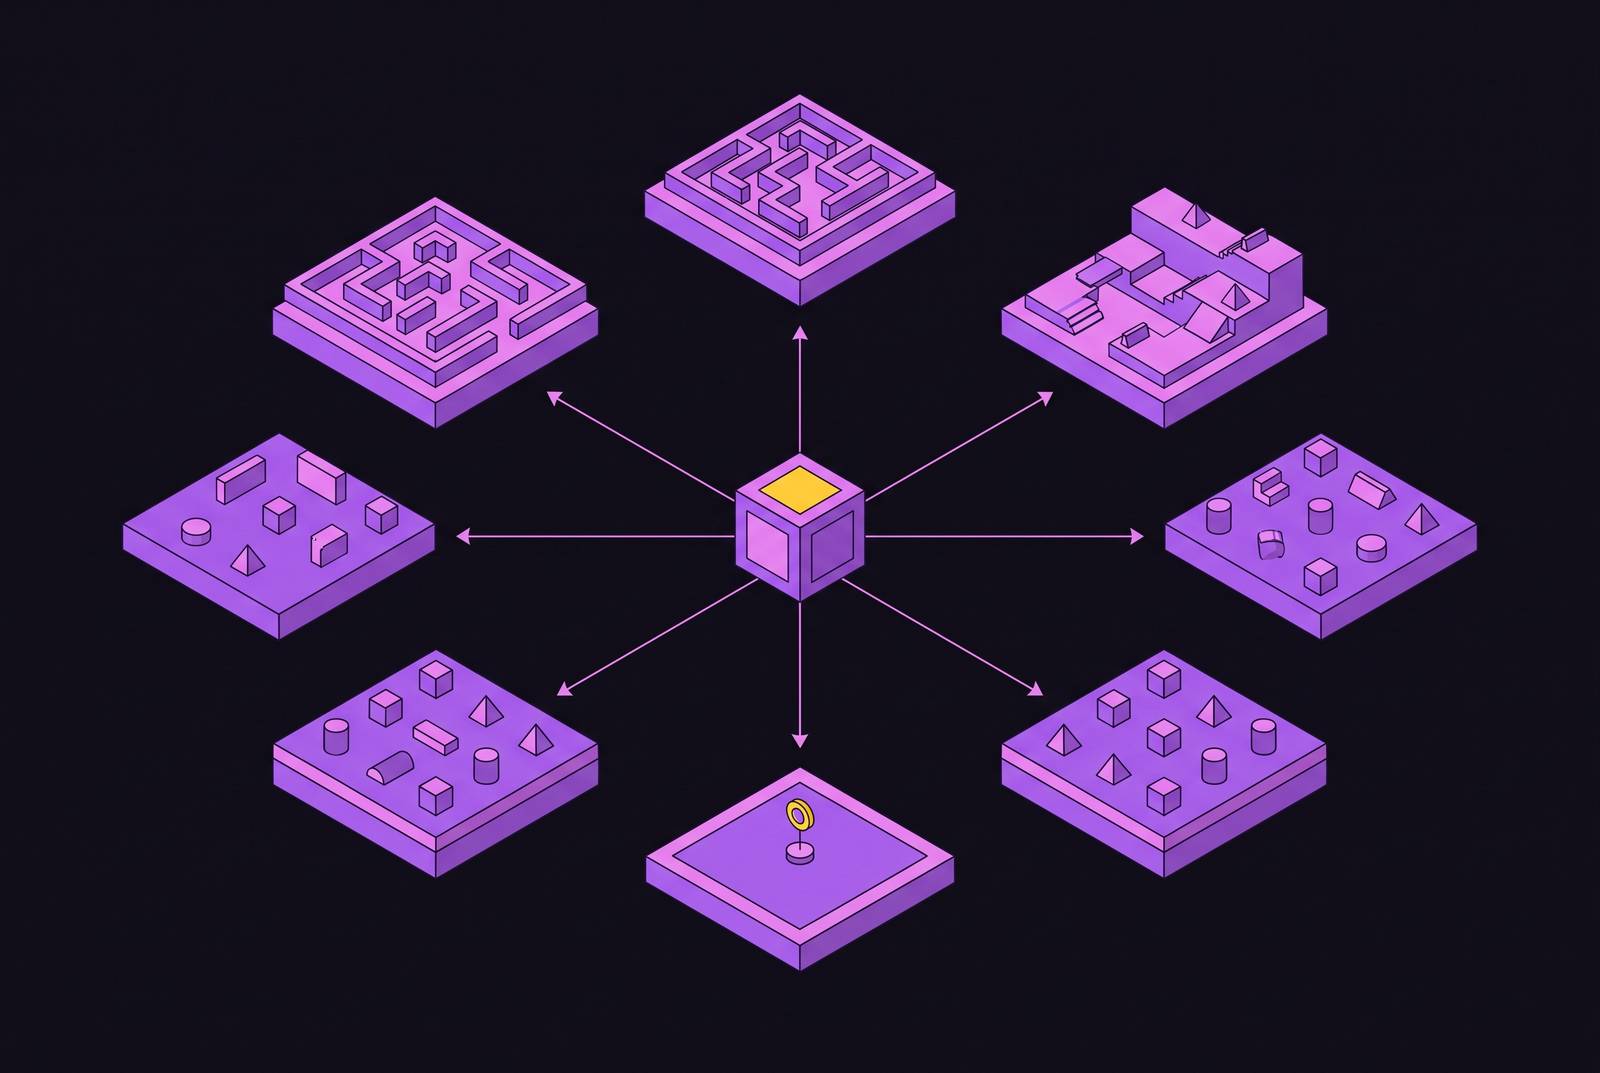
Brittle versus robust policies across unseen variation
Zero-shot transfer in game AI means training a policy on one set of procedurally generated levels and deploying it, unmodified, into levels it has never seen. No retraining, no fine-tuning, no second chance to adjust. The policy either holds up on first contact with the unknown or it collapses, and that binary condition describes, with unsettling accuracy, what happens when a go-to-market team takes a playbook built for one market and points it at another.
Procedural generation exists to prevent memorization. Game researchers randomize layout, enemy placement, obstacle density, and reward structure because an agent trained on a fixed set of levels finds shortcuts. It learns incidental correlations specific to those levels and rides them to strong scores right up until the generator produces a level that breaks the pattern. The agent never learned to navigate. It learned to navigate those levels, and the difference stays invisible until training ends and deployment starts.
Zero-shot transfer belongs in a harder category than few-shot adaptation or domain randomization, both of which let a policy sample a handful of new conditions before it has to perform for real. Zero-shot removes the sampling step. The gap between what the agent memorized and what a new level demands can be arbitrarily wide, and even minor surface-level changes in a new level can collapse performance that looked, moments earlier, close to perfect.
Brittleness and robustness come down to what a policy actually encodes, nothing more mysterious than that. A brittle policy has learned positional cues, pixel-level patterns, or exploits against the reward function, none of which mean anything outside the narrow band of conditions it trained on. A robust one has learned something closer to the real structure of the problem: spatial relationships, enemy behavior logic, resource tradeoffs, abstractions that hold even when the surface details change.
Four design choices separate the two, and training environment diversity matters most of all. A policy exposed to a wide, varied distribution of levels generalizes better than one trained on a narrow set, even a very large narrow set. Volume does not substitute for variety. Representation choice comes next, because what the agent observes shapes what it can learn: feature representations built around relational structure transfer across levels, while raw pixel input tends to encode surface noise that breaks the moment the level changes. Dense, environment-specific rewards teach an agent to find local shortcuts fast, while sparse rewards tied to abstract goals push it toward something closer to genuine understanding, even though that understanding becomes visible only after more training time; reward shaping therefore cuts both ways. Architecture and regularization choices decide whether the network can memorize irrelevant correlations in the first place, or gets structurally blocked from doing so.
None of this resolves the underlying tension, and no clever fix makes it disappear. More training on a fixed distribution keeps improving in-distribution performance while quietly raising the risk of brittleness on everything outside it. That tradeoff is structural. It does not go away with a bigger dataset or a more elegant architecture, and anyone building a policy, in a game engine or anywhere else, has to decide up front how much in-distribution performance they are willing to sacrifice for one that survives contact with the unfamiliar.
How GTM systems fail the same way brittle game policies fail
A go-to-market playbook built for one ICP, tuned against one campaign window, then deployed unchanged into a new vertical or a colder buying climate, is a brittle policy in every sense that matters. It has learned the sales equivalent of positional cues: this subject line worked for this persona, this qualification threshold matched this product line, this data source reliably surfaced the right contacts. None of that is generalizable logic. It's pattern-matching against a training distribution that happened to hold still long enough to look like a strategy.
The failure appears in predictable places. Outbound sequences tuned to a single ICP go tone-deaf the moment a team moves upmarket or into an adjacent industry, because the pain points that opened doors at 50-person companies don't land the same way at a much larger enterprise. Qualification criteria calibrated against one product line misfire when a new offering pulls in a buyer type the scoring model was never built to recognize. Enrichment workflows anchored to a single data source degrade quietly when that source goes stale or the target market shifts underneath it, and nobody notices until the pipeline numbers already look wrong.
Personalization at the surface level gets mistaken for generalization constantly, and the confusion costs real pipeline. Swapping in a company name, a job title, a recent funding announcement is pattern-matching dressed up as customization, and it collapses the instant a buyer deviates even slightly from the template it was built against. That's the sales equivalent of an agent recognizing a pixel pattern instead of understanding a level layout: it works until it doesn't, and there's no warning in between.
Pipeline dries up for reasons that get misdiagnosed constantly. Teams assume the market disappeared when really the playbook was never built to generalize past its original conditions, so they rebuild from scratch, again, instead of compounding on logic that would have carried forward. A fragmented stack makes the misdiagnosis worse. When data lives in one tool, sequencing in another, and outcomes sit in a CRM nobody opens until the quarterly review, no feedback loop exists to catch drift early. The policy drifts out of distribution silently, and the first signal anyone gets is a pipeline number that already collapsed weeks ago.
Structural principles that make GTM playbooks generalize across new markets and personas
The fix maps almost directly onto the RL playbook, point for point. Training distribution diversity becomes ICP breadth: a playbook tested across multiple verticals, deal sizes, and persona types survives an unfamiliar segment far more often than one validated through A/B tests run on a single narrow group. Running ten variants of the same test against the same ten accounts is the GTM equivalent of training an agent on ten levels and calling the job finished, and it should not pass for rigor.
Representation choice becomes a question of what the system actually knows about a buyer, and relational signal beats surface signal every time this gets tested. Title, company size, and headcount are fragile by nature, shifting with a reorg, a funding round, or a downturn, so a policy built on them inherits that fragility wholesale. Relational and behavioral signals hold up better, because they describe the underlying problem a buyer has rather than a snapshot of who they happen to be this quarter: buying committee structure, engagement pattern, current technology stack, a recent hiring signal in a relevant function. A platform built on waterfall enrichment and layered buying-signal data, instead of a single static source, gives a policy a richer observation space to reason from, the same way relational feature representation gives a game agent something more durable to learn than raw pixels.
Reward shaping becomes visible in message design, and the two approaches here are not equally valid. Sequences that open by naming a category of problem the buyer is likely facing transfer across personas far better than sequences that open with a flattering line about the company or a rundown of product features. The first approach encodes the structure of the buyer's situation. The second encodes a local pattern that happened to work once, on someone else, in a different context, and has no reason to work again here.
Regularization becomes deliberate constraint. Capping how many steps in a sequence can be persona-specific forces a team to figure out, explicitly, what has to hold universal across every version of the playbook. Periodic generalization tests, running a playbook against a segment it was never built for and measuring how badly it degrades, function exactly like evaluating a trained policy against held-out levels. One idea governs all four principles: encode the logic of the buyer's situation rather than the surface details of the last campaign that happened to work.
The feedback loop requirement for GTM platform architecture
A reinforcement learning policy that can't observe the consequences of its own actions has no way to update its internal model. It stays exactly as brittle as it started, indefinitely, because nothing pulls it toward improvement. Sales execution systems that lack closed-loop signal get stuck in the same place, for the same structural reason, and no amount of rep effort fixes what is fundamentally a wiring problem.
Closed-loop signal in GTM means reply rates, meeting conversions, and deal outcomes flow back into the same system that generated the sequence, not into a spreadsheet somebody reviews once a quarter after the damage is done. It means enrichment quality gets flagged the moment a contact's data proves stale or a firmographic assumption turns out wrong, so the system adjusts instead of silently repeating the mistake against the next thousand contacts. It also means the system retains outcome signal across campaigns rather than resetting to zero every time someone launches a new sequence.
A fragmented stack makes closing this loop close to impossible. When outreach lives in one tool, enrichment data in another, and outcomes sit inside a CRM that only gets touched at reporting time, the feedback signal arrives late, arrives partial, and gets manually stitched together by whoever has six other things due that day. A system built that way just executes and waits. It never learns anything, so it never generalizes.
An end-to-end platform, where prospecting, enrichment, sequencing, dialing, and deal management share one data layer, is the architectural precondition for a GTM policy that can improve on its own. This is the strongest argument against stitching together five point solutions and calling it a stack: Apollo's architecture connects data, intelligence, and execution with buying-signal feedback running through the same system, the direct analog to the observation, action, and reward loop that makes generalization possible in reinforcement learning. Without that wiring, there's no loop left to close, no matter how good any individual tool in the stack happens to be.
How AI agents extend zero-shot capability in practice
In game AI, zero-shot performance is determined entirely by whatever the policy learned during training, with no opportunity to adapt at deployment. In GTM, the policy itself can reason, and that changes the shape of the problem. An AI agent dropped into an unfamiliar segment isn't limited to replaying whatever pattern worked last quarter. It can build a working model of the new environment on the spot.
That looks like a specific sequence of actions. The agent receives a new target segment or persona with no pre-built sequence waiting for it. It pulls from the platform's enrichment and signal data to construct a hypothesis about what this particular buyer actually cares about. It drafts outreach grounded in the structure of that buyer's likely situation, rather than reaching for a template lifted wholesale from a different campaign that happened to work somewhere else. Then it watches early engagement signals as they come in, surfacing adjustment recommendations before the sequence has even finished running, instead of waiting for a postmortem three weeks later.
The distinction that actually matters, and the one most teams get backwards, is between AI that suggests copy and AI that executes a policy. Copy-suggestion tools reproduce the training distribution: they're autocomplete with better branding, and no amount of polish changes that. An agent that researches a segment, builds its own list, writes outreach specific to the context it just uncovered, and adjusts based on the response it gets back is doing something structurally different. It's generalizing, not autocompleting, and that gap is the entire argument here. Agent memory compounds the advantage over time, because each new market or persona the system touches adds to its cross-segment understanding, which makes the next zero-shot deployment more reliable than the last, not equally uncertain.
That shifts what a human is actually for in the loop. The job moves from rebuilding the playbook for every new environment to setting goals, reviewing the agent's reasoning, and stepping in at the decision points that genuinely require judgment. Those moments don't disappear. They get rarer and more concentrated.
What it takes to test whether a GTM policy generalizes before it fails in the field
RL researchers don't take a policy's word for it. They test generalization directly, by evaluating performance on held-out levels the agent never trained on, and the gap between training performance and held-out performance tells them whether the policy learned anything durable.
GTM teams can run the same test before committing a playbook to a new vertical or persona: a controlled probe against a small, signal-rich sample that sits genuinely outside the playbook's original distribution. Three things matter in that probe, and the third one gets skipped far too often. Engagement pattern comes first: does the sequence provoke the response it's supposed to from this new persona, or does it produce confusion and silence, the sales equivalent of an agent wandering into a wall it's never seen before. Qualification signal quality comes second: are the leads responding to the sequence actually matching the ICP hypothesis, or is the playbook attracting exactly the wrong kind of buyer. Step-level drop-off comes third, and it's the most diagnostic of the three, because it shows precisely where the sequence breaks down, which in turn reveals which elements were structurally sound and which were surface-specific the entire time.
Two disciplines keep this from turning into an endless rebuild cycle. The first is separating the invariant core of a playbook, its problem framing, its value logic, its call-to-action structure, from the variable surface: industry language, persona-specific pain points, channel mix. The second is documenting what each probe actually revealed, so the system accumulates that knowledge instead of leaving it locked inside one rep's head or one campaign retro nobody reads again.
A perfect policy for every environment a team might encounter does not exist, and chasing one wastes the exact resources a probe like this is meant to save. The real goal is a policy architecture that degrades gracefully instead of catastrophically, signals clearly when it's operating out of distribution, and recovers faster than a system rebuilt from zero every time the market shifts. That's the standard a well-designed GTM platform, with closed-loop signal and agent memory built into its architecture rather than bolted on after the fact, has to meet.